6.4.6. 附录
6.4.6.1. Eager 模式
和 PyTorch 官方
与 fx 模式的区别
在 horizon_plugin_pytorch 中
eager 模式
仅 支持 module 形式 的 算子。您 需要 手动 将 浮点 模型 中 的 函数 形式 的 算子 替换 为 PyTorch 中 Module 类型 的 算子 或者 是 horizon_plugin_pytorch 中 定义 的 专有 算子,包括 但 不 限于:
| 原始 |
需要 |
|---|---|
| torch.nn.functional.relu | torch.nn.ReLU() |
| a + b torch.add |
horizon.nn.quantized.FloatFunctional().add |
| Tensor.exp | horizon.nn.Exp() |
| torch.nn.functional.interpolate | horizon.nn.Interpolate() |
您
必须 手动 定义 需要 融合 的 算子,并 显示 调用 融合 函数,调用 时 也 需 指定 使用 horizon_plugin_pytorch 中 提供 的 fuser_func。如下所示:
import torch
from torch import nn
import horizon_plugin_pytorch as horizon


class ConvBNReLU(nn.Sequential):
    def __init__(self, in_channels, out_channels, kernel_size):
        super(ConvBNReLU, self).__init__(
            nn.Conv2d(
            in_channels=in_channels,
            out_channels=out_channels,
            kernel_size=kernel_size
            ),
            nn.BatchNorm2d(num_features=out_channels),
            nn.ReLU()
        )

    # 指定可以 fuse 的算子
    def fuse_model(self):
        torch.quantization.fuse_modules(
            self,
            ['0', '1', '2'],
            inplace=True,
            # 指定 horizon_plugin_pytorch 中提供的 fuse 函数
            fuser_func=horizon.quantization.fuse_known_modules,
        )

float_model = ConvBNReLU(1, 1, 1)
# 需要显示调用 fuse 函数
float_model.fuse_model()

print(float_model)
# ConvBNReLU(
#   (0): ConvReLU2d(
#     (0): Conv2d(1, 1, kernel_size=(1, 1), stride=(1, 1))
#     (1): ReLU()
#   )
#   (1): Identity()
#   (2): Identity()
# )
使用流程
Eager 模型
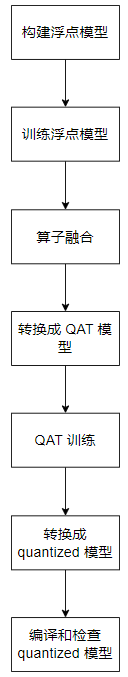
构建浮点模型
Eager 模式
在
网络 中 插入 量化 和 反 量化 节点。一般 在 浮点 模型 的 开始 需要 插入 一个 量化 节点,在 结束 部分 需要 插入 一个 反 量化 节点。当 浮点 模型 在 被 转为 待 量化 训练 的 QAT 模型 之后,插入 的 量化 节点 将会 对 输入 进行 量化 操作; 一些
浮点 的 函数 形式 算子 需要 替换 为 Pytorch 中 继承 自 Module 的 算子 或是 Plugin 提供 的 一些 专有 算子; 定义
浮点 算子 的 融合 函数,对 可以 融合 的 算子 进行 融合。
import torch
import torch.optim as optim
import horizon_plugin_pytorch as horizon
import os
from torch import nn
from torchvision import datasets, transforms
from torch.quantization import DeQuantStub
from horizon_plugin_pytorch.quantization import QuantStub

class ConvBNReLU(nn.Sequential):
    def __init__(self, in_channels, out_channels, kernel_size):
        super(ConvBNReLU, self).__init__(
            nn.Conv2d(
            in_channels=in_channels,
            out_channels=out_channels,
            kernel_size=kernel_size
            ),
            nn.BatchNorm2d(num_features=out_channels),
            nn.ReLU()
        )

    # 指定可以融合的浮点算子
    def fuse_model(self):
        torch.quantization.fuse_modules(
            self,
            ['0', '1', '2'],
            inplace=True,
            fuser_func=horizon.quantization.fuse_known_modules,
        )

class ClassiFier(nn.Module):
    def __init__(self, in_channels, out_channels):
        super(ClassiFier, self).__init__()
        self.conv = nn.Conv2d(in_channels, out_channels, 1)

    def forward(self, data):
        return self.conv(data)

# 构建浮点模型
class Net(nn.Module):
    def __init__(self):
        super(Net, self).__init__()
        self.conv0 = ConvBNReLU(1, 10, 5)
        self.max_pool = nn.MaxPool2d(kernel_size=2)
        self.conv1 = ConvBNReLU(10, 20, 5)
        self.avg_pool = nn.AvgPool2d(kernel_size=8)
        self.classifier = ClassiFier(20, 10)
        # 为了适配 bpu,当从摄像头获取输入时 QuantStub 的 scale 必须显示地设置成 1/128
        self.quant = QuantStub(scale=1/128)
        self.dequant = DeQuantStub()

    def forward(self, x):
        # 插入量化节点对输入进行量化
        x = self.quant(x)
        x = self.conv0(x)
        x = self.max_pool(x)
        x = self.conv1(x)
        x = self.avg_pool(x)
        x = self.classifier(x)
        # 插入反量化节点对输出进行反量化
        x = self.dequant(x)
        return x

    # 定义融合函数
    def fuse_model(self):
        from horizon_plugin_pytorch import quantization

        for m in self.modules():
            if type(m) == ConvBNReLU:
                m.fuse_model()
浮点模型预训练
train_batch_size = 16
test_batch_size = 16
epoch_num = 1
neval_batches = 1
model_file = 'model.pt'

class AverageMeter(object):
    """Computes and stores the average and current value"""

    def __init__(self, name, fmt=":f"):
        self.name = name
        self.fmt = fmt
        self.reset()

    def reset(self):
        self.val = 0
        self.avg = 0
        self.sum = 0
        self.count = 0

    def update(self, val, n=1):
        self.val = val
        self.sum += val * n
        self.count += n
        self.avg = self.sum / self.count

    def __str__(self):
        fmtstr = "{name} {val" + self.fmt + "} ({avg" + self.fmt + "})"
        return fmtstr.format(**self.__dict__)

criterion = nn.CrossEntropyLoss()

def accuracy(output, target, topk=(1,)):
    """Computes the accuracy over the k top predictions for the specified
    values of k
    """
    with torch.no_grad():
        maxk = max(topk)
        batch_size = target.size(0)

        _, pred = output.topk(maxk, 1, True, True)
        pred = pred.t()
        correct = pred.eq(target.view(1, -1).expand_as(pred))

        res = []
        for k in topk:
            correct_k = correct[:k].reshape(-1).float().sum(0, keepdim=True)
            res.append(correct_k.mul_(100.0 / batch_size))
        return res


def get_train_data_loader():
    train_loader = torch.utils.data.DataLoader(
        datasets.MNIST(
            'mnist_data',
            train=True,
            download=True,
            transform=transforms.Compose(
                [transforms.ToTensor(),
                 transforms.Normalize((0.5,), (0.5,))]
            )
        ),
        batch_size=train_batch_size,
        shuffle=True,
    )
    return train_loader

def get_test_data_loader():
    train_loader = torch.utils.data.DataLoader(
        datasets.MNIST(
            'mnist_data',
            train=False,
            download=True,
            transform=transforms.Compose(
                [transforms.ToTensor(),
                 transforms.Normalize((0.5,), (0.5,))]
            )
        ),
        batch_size=test_batch_size,
        shuffle=True,
    )
    return train_loader

data_loader = get_train_data_loader()
test_loader = get_test_data_loader()

def train(model, device, optimizer, epoch):
    global min_loss
    model.train()
    for batch_idx, (data, target) in enumerate(data_loader):
        data = data.to(device)
        target = target.to(device)
        output = model(data)
        output = output.view(-1, 10)
        loss = criterion(output, target)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()
        if batch_idx %  100 == 0:
            print ('Train Epoch: {} batch {} \t Loss: {:.6f}'.
                format(epoch, batch_idx, loss.item()))

def evaluate(model, device, neval_batches):
    model.eval()
    top1 = AverageMeter("Acc@1", ":6.2f")
    top5 = AverageMeter("Acc@5", ":6.2f")
    tested_batches = 0
    with torch.no_grad():
        for batch_idx, (data, target) in enumerate(test_loader):
            tested_batches += 1
            data = data.to(device)
            target = target.to(device)
            output = model(data)
            output = output.view(-1, 10)
            loss = criterion(output, target)
            acc1, acc5 = accuracy(output, target, topk=(1, 5))
            top1.update(acc1[0], data.size(0))
            top5.update(acc5[0], data.size(0))
            if tested_batches >= neval_batches:
                return top1, top5

    return top1, top5


def train_float_model(device):
    model = Net().to(device)
    optimizer = optim.SGD(model.parameters(), lr=0.001, momentum=0.1)
    for nepoch in range(epoch_num):
        train(model, device, optimizer, nepoch)
        top1, top5 = evaluate(model, device, neval_batches)
        print(
            "float training Epoch %d :float evaluation accuracy on %d images, \
            %2.2f" % (nepoch, neval_batches * test_batch_size, top1.avg)
        )
    torch.save(model.state_dict(), model_file)

train_float_model(torch.device('cuda'))
如果
def load_model():
    model = Net()
    state_dict = torch.load(model_file)
    model.load_state_dict(state_dict)
    model.to('cpu')
    return model

qat_model = load_model()
设置 BPU 架构
# 设置 march **X3** 设置BERNOULLI2, **X5** 设置为BAYES_E。
horizon.march.set_march(horizon.march.March.BAYES_E)
算子融合
qat_model.fuse_model()
浮点模型转为量化模型
def load_and_prepare_qat_model(device):
    # 加载预训练浮点模型
    global qat_model
    qat_model = qat_model.to(device)
    top1, top5 = evaluate(qat_model, device, neval_batches)
    print(
        "float evaluation accuracy on %d images, \
        %2.2f" % (neval_batches * test_batch_size, top1.avg)
    )
    # 设置量化训练的量化参数用于指定如何对算子的权值 (weight) 和输出进行量化
    qat_model.qconfig = horizon.quantization.get_default_qat_qconfig()
    # 取消输出层的量化功能提高输出的准确性
    qat_model.classifier.qconfig = \
        horizon.quantization.get_default_qat_out_qconfig()
    # 将浮点模型转化为量化模型
    horizon.quantization.prepare_qat(qat_model, inplace=True)
    print(
        "After preparation for QAT, note fake-quantization modules \n",
        qat_model.conv0,
    )
    qat_model = qat_model.to(device)

load_and_prepare_qat_model(torch.device('cuda'))
量化训练
def quantization_training(device):
    # 对量化模型进行量化训练
    optimizer = optim.SGD(qat_model.parameters(), lr=0.0001)
    for nepoch in range(1):
        train(qat_model, device, optimizer, nepoch)
        # 训练一个轮次的量化模型进行评测
        top1, top5 = evaluate(qat_model, device, neval_batches)
        print(
            "QAT Epoch %d :float evaluation accuracy on %d images, %2.2f"
            % (nepoch, neval_batches * test_batch_size, top1.avg)
        )

quantization_training(torch.device('cuda'))
量化模型转为定点模型
quantized_model = horizon.quantization.convert(
    qat_model.eval(), inplace=False
)
对定点预测模型进行检查和编译
def compile_quantized_model(device):
    example_input = torch.ones(size=(neval_batches, 1, 28, 28), device=device)
    traced_model = torch.jit.trace(quantized_model, example_input)
    top1, top5 = evaluate(traced_model, device, neval_batches)
    print(
        "Traced : int evaluation accuracy on %d images, %2.2f"
        % (neval_batches * test_batch_size, top1.avg)
    )

    # 检查模型是否能够被 hbdk 编译。hbdk 是一个对定点模型进行编译的工具。
    horizon.quantization.check_model(quantized_model, example_input, advice=1)
    hbdk_dir = "hbdk_model"
    if not os.path.exists(hbdk_dir):
        os.mkdir(hbdk_dir)

    # 编译模型,hbdk_model 目录下的 model.hbm 就是编译得到的上板模型
    horizon.quantization.compile_model(
        traced_model, [example_input], opt=2, hbm=hbdk_dir + "/model.hbm"
    )
    # 对模型进行静态性能分析
    horizon.quantization.perf_model(
        traced_model,
        [example_input],
        opt=2,
        input_source=["pyramid"],
        layer_details=True,
        out_dir=hbdk_dir,
    )
    horizon.quantization.visualize_model(
        traced_model,
        [example_input],
        save_path=hbdk_dir + "/model.svg",
        show=False,
    )

compile_quantized_model(torch.device('cuda'))
6.4.6.2. 支持的公版算子
综合说明
除
特别 说明,Bernoulli2 架构 限制 算子 的 输入输出 均 为 4 维。 在 eager 模式
中,部分 算子 需要 手动 替换,fx 模式 无需 手动 替换 算子。 以下
支持 的 算子 默认 为 不 进行 算子 融合,对于 可 进行 融合 的 算子(如 (conv,bn),relu)),参考算子 融合 章节。在
预测 阶段,透传 的 算子(例如 Identity,Dropout),在 部署 时会 被 优化 掉。
torch function 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torch.abs | 不 |
qint8, qint16 | 同 |
||||
| torch.acos | horizon.nn.Acos | 不 |
qint8, qint16 | qint8, qint16 | 底层 |
||
| torch.acosh | horizon.nn.Acosh | 不 |
参考 torch.acos | ||||
| torch.add | torch.nn.quantized.FloatFunctional 或 horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | in_channel<=2048,不 |
qint8, qint16 | qint8, qint16 | 支持 |
| torch.argmax | 参考 torch.max | 参考 torch.max | |||||
| torch.argmin | 参考 torch.max | 参考 torch.max | |||||
| torch.asin | horizon.nn.Asin | 不 |
参考 torch.acos | ||||
| torch.asinh | horizon.nn.Asinh | 不 |
参考 torch.acos | ||||
| torch.atan | horizon.nn.Atan | 不 |
参考 torch.acos | ||||
| torch.atanh | horizon.nn.Atanh | 不 |
参考 torch.acos | ||||
| torch.cat | torch.nn.quantized.FloatFunctional 或 horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | qint8, qint16 | qint8, qint16 | input shape: [N, C, H, W], N<=4096, HWC<=65536, 2<=input number<=1024 | |
| torch.ceil | horizon.nn.Ceil | 不 |
qint8, qint16 | 同 |
int8下 |
||
| torch.clamp | 不 |
qint8, qint16 | 同 |
支持min和max的 |
|||
| torch.clip | 不 |
参考 torch.clamp | |||||
| torch.cos | horizon.nn.Cos | 不 |
参考 torch.acos | ||||
| torch.cosh | horizon.nn.Cosh | 不 |
参考 torch.acos | ||||
| torch.div | horizon.nn.Div | 不 |
qint16 | qint16 | |||
| torch.eq | 不 |
qint8, qint16 | qbool | ||||
| torch.erf | horizon.nn.Erf | 不 |
参考 torch.acos | ||||
| torch.exp | horizon.nn.Exp | qint8 | qint8 | 使用 |
参考 torch.acos | ||
| torch.floor | horizon.nn.Floor | 不 |
qint8, qint16 | 同 |
int8下 |
||
| torch.gather | 不 |
qint8, qint16, qint32 | 同 |
||||
| torch.ge | 不 |
参考 torch.eq | |||||
| torch.greater | 不 |
参考 torch.eq | |||||
| torch.greater_equal | 不 |
参考 torch.eq | |||||
| torch.gt | 不 |
参考 torch.eq | |||||
| torch.le | 不 |
参考 torch.eq | |||||
| torch.less | 不 |
参考 torch.eq | |||||
| torch.less_equal | 不 |
参考 torch.eq | |||||
| torch.log | horizon.nn.HardLog | 不 |
参考 torch.acos | ||||
| torch.lt | 不 |
参考 torch.eq | |||||
| torch.matmul | horizon.nn.quantized.FloatFunctional | qint8 | qint8, qint32 | qint8, qint16, qint32 | input shape: [N, C, H, W], input_size<1 G bytes, N<=4096, C, H, W<=8192. | ||
| torch.max | qint8 | 同 |
只能 |
qint8, qint16 | out: qint8, qint16 index: int32 | index 只能 |
|
| torch.maximum | horizon.nn.quantized.FloatFunctional | 不 |
input: qint8, qint16 other: qint8, qint16 |
qint8, qint16 | |||
| torch.mean | horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | 只 |
qint8, qint16 | qint8, qint16 | 支持 |
| torch.min | 不 |
参考 torch.max | |||||
| torch.minimum | horizon.nn.quantized.FloatFunctional | 不 |
参考 torch.maximum | ||||
| torch.mul | torch.nn.quantized.FloatFunctional 或 horizon.nn.quantized.FloatFunctional | 参考 torch.add | 参考 torch.add | ||||
| torch.pow | horizon.nn.Pow | 不 |
参考 torch.acos | ||||
| torch.reciprocal | horizon.nn.Reciprocal | 不 |
参考 torch.acos | ||||
| torch.selu | horizon.nn.Selu | 不 |
参考 torch.acos | ||||
| torch.sin | horizon.nn.Sin | 不 |
参考 torch.acos | ||||
| torch.sinh | horizon.nn.Sinh | 不 |
参考 torch.acos | ||||
| torch.split | qint8, qint16 | 同 |
qint8, qint16 | 同 |
|||
| torch.sqrt | horizon.nn.Sqrt | 不 |
参考 torch.acos | ||||
| torch.sub | horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | in_channel<=2048 | qint8, qint16 | qint8, qint16 | 支持 |
| torch.sum | horizon.nn.quantized.FloatFunctional | qint8 | qint8, qint32 | 只 |
qint8, qint16 | qint8, qint16 | 仅 |
| torch.tan | horizon.nn.Tan | 不 |
参考 torch.acos | ||||
| torch.topk | 不 |
qint8, qint16, qint32 | 同 |
torch.nn.functional function 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torch.nn.functional.grid_sample | 不 |
不 |
不 |
input:qint8 grid: qint8, qint16 |
qint8 | 输入 shape: [N, C, H, W], 1<=H, W<=1024 且 HW<=7201024; grid 支持 qint8 和 qint16,只 |
|
| torch.nn.functional.interpolate | qint8 | qint8 | 支持 nearest 和 billinear 插值 |
qint8 | qint8 | 只 |
|
| torch.nn.functional.pad | 不 |
不 |
不 |
qint8, qint16 | 同 |
不 |
|
| torch.nn.functional.relu | torch.nn.ReLU | qint8 | qint8 | qint8 | 同 |
Conv2d+BN+ReLU 这种 |
|
| torch.nn.functional.relu6(fused) | torch.nn.ReLU6 | qint8 | 同 |
torch.nn Module 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torch.nn.AdaptiveAvgPool2d | 不 |
不 |
不 |
qint8 | 同 |
使用 AvgPool2d 非 |
|
| torch.nn.AvgPool2d | qint8 | 同 |
1<=kernel<=7,1<=stride<=185 | 1<=kernel, stride, padding<=256; | |||
| torch.nn.BatchNorm2d | BatchNorm2d 在 QAT 阶段 |
qint8 | qint8 | BatchNorm2d 在 QAT 阶段 |
|||
| torch.nn.BatchNorm3d | BatchNorm3d 在 QAT 阶段 |
qint8 | qint8 | BatchNorm3d 在 QAT 阶段 |
|||
| torch.nn.ChannelShuffle | qint8 | 同 |
qint8, qint16 | 同 |
shuffle_index 中 |
||
| torch.nn.ConstantPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | |||
| torch.nn.Conv2d | qint8 | qint8,qint32 | input: qint8, qint16; weight: qint8; bias: qint32 | qint8, qint16,qint32 | out_channel<=8192,作为 |
||
| torch.nn.Conv3d | 不 |
不 |
不 |
input: qint8, weight: qint8, bias: qint32 | qint8 | input: [N, C, D, H, W] int8, N<=128; H, W, D, C<=65536; weight: [C_o, C_i, D, H, W] int8, N, C<=65536, D, H<=9, W<=8191; bias: int32; output: [N, C, D, H, W] int8, int16, int32; stride: [D, H, W], D, H, W 等于 1 或 2, 并且 D, H, W 相同; padding: [D, H, W], D<=kernel_d/2, H<=kernel_h/2, W<=kernel_w/2(kernel_w 指 weight W 维 |
|
| torch.nn.ConvTranspose2d | qint8 | qint8 | 2<=kernel<= 14.channel<=2048. padding H*W=[0, (kernel_h-1)/2] * [0, (kernel_w-1)/2] 2<=stride<=4, dilation=(1, 1) | qint8 | qint8 | 输入 shape: [N, C, H, W], 1<=N<=128, 1<=channel<=2048; weight_shape: [N, C, H, W], 1<=N, C<=2048, 2<=H, W<=14, weight_size<=65535; kernel>=stride, 1<=stride<=14, 1<=out_channel<=2048, in_channel<=2048 pad<=kernel/stride, 0<=out_pad<=1; bias 类型 |
|
| torch.nn.Dropout | qint8, qint16,qint32 | 同 |
qint8, qint16,qint32 | 同 |
|||
| torch.nn.Dropout2d | qint8, qint16,qint32 | 同 |
qint8, qint16,qint32 | 同 |
|||
| torch.nn.ELU | 不 |
不 |
不 |
参考 torch.acos | 参考 torch.acos | ||
| torch.nn.GELU | 参考 torch.exp | 参考 torch.exp | 参考 torch.exp | 参考 torch.acos | 参考 torch.acos | ||
| torch.nn.GLU | 不 |
不 |
参考 torch.acos | 参考 torch.acos | |||
| torch.nn.HardSigmoid | 不 |
不 |
不 |
参考 torch.acos | 参考 torch.acos | ||
| torch.nn.Identity | qint8, qint16,qint32 | 同 |
qint8, qint16,qint32 | 同 |
|||
| torch.nn.Layernorm | 不 |
不 |
不 |
qint8 | qint8, qint16 | 底层 |
|
| torch.nn.LeakyReLU | 不 |
不 |
不 |
参考 torch.acos | 参考 torch.acos | ||
| torch.nn.Linear | 不 |
不 |
不 |
input: qint8; weight:qint8; bias: qint32 | qint8 | in_features <= 8192, out_features <= 8192. | |
| torch.nn.LSTMCell | 不 |
不 |
不 |
qint8, qint16 | qint8, qint16 | 输入 |
|
| torch.nn.MaxPool2d | qint8 | 同 |
1<=kernel<=64, 1<=stride<=256, padding>=0 | qint8 | 同 |
input_shape: [N, C, H, W], 1<=H, W, C<=8192;1<=kernel, stride<=256; 0<=padding<=255; | |
| torch.nn.MultiheadAttention | 不 |
不 |
不 |
qint8,qint16 | qint8,qint16 | 不 |
|
| torch.nn.PixelShuffle | qint8, qint16 | 同 |
qint8,qint16 | 同 |
|||
| torch.nn.PixelUnshuffle | qint8, qint16 | 同 |
qint8,qint16 | 同 |
|||
| torch.nn.PReLU | 不 |
不 |
不 |
参考 torch.acos | 参考 torch.acos | ||
| torch.nn.ReLU | qint8 | 同 |
qint8,qint16 | 同 |
|||
| torch.nn.ReLU6 | qint8 | 同 |
qint8,qint16 | 同 |
|||
| torch.nn.ReplicationPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | 参考 torch.nn.ZeroPad2d | ||
| torch.nn.Sigmoid | 参考 torch.exp | 参考 torch.exp | 参考 torch.exp | 参考 torch.acos | 参考 torch.acos | ||
| torch.nn.SiLU | 参考 torch.exp | 参考 torch.exp | 参考 torch.exp | 参考 torch.acos | 参考 torch.acos | ||
| torch.nn.Softmax | 不 |
不 |
不 |
qint8 | qint8, qint16 | 使用 |
|
| torch.nn.Softplus | 不 |
不 |
不 |
参考 torch.acos | 参考 torch.acos | ||
| torch.nn.SyncBatchNorm | qint8 | qint8 | 使用 torch.nn.Conv2d 拼凑 | qint8 | qint8 | 使用 torch.nn.Conv2d 拼凑 | |
| torch.nn.Tanh | 参考 torch.exp | 参考 torch.exp | 参考 torch.exp | 参考 torch.acos | 参考 torch.acos | 参考 torch.acos | |
| torch.nn.Upsample | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | |
| torch.nn.UpsamplingBilinear2d | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | |
| torch.nn.UpsamplingNearest2d | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | 参考 torch.nn.functional.interpolate | |
| torch.nn.ZeroPad2d | qint8 | 同 |
qint8, qint16 | 同 |
torch.quantization Module 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torch.quantization.DeQuantStub | qint8,qint16,qint32 | float32 | 典型 |
qint8,qint16,qint32 | float32 | 典型 |
|
| torch.quantization.QuantStub | horizon.quantization.QuantStub | float32 | qint8,qint16 | 典型 |
float32 | qint8,qint16 | 典型 |
torch.Tensor method 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torch.Tensor.getitem | qint8, qint16, qint32 | 同 |
|||||
| torch.Tensor.transpose | 不 |
不 |
不 |
qint8, qint16, qint32 | Tensor.dtype | 不 |
|
| torch.Tensor.argmax | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | |
| torch.Tensor.argmin | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | 参考 torch.max | |
| torch.Tensor.clamp | 不 |
不 |
不 |
qint8, qint16 | Tensor.dtype | dim <= 10, 1 <= each_dim_size < 65536 | |
| torch.Tensor.clip | 不 |
不 |
不 |
参考 torch.Tensor.clip | 参考 torch.Tensor.clip | 参考 torch.Tensor.clip | |
| torch.Tensor.eq | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.expand | 不 |
不 |
不 |
qint8, qint16 | Tensor.dtype | ||
| torch.Tensor.ge | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.greater | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.greater_equal | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.gt | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.le | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.less | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.less_equal | 不 |
不 |
不 |
参考 torch.eq | 参考 torch.eq | 参考 torch.eq | |
| torch.Tensor.max | 不 |
不 |
不 |
参考 torch.max | 参考 torch.max | 参考 torch.max | |
| torch.Tensor.min | 不 |
不 |
不 |
参考 torch.max | |||
| torch.Tensor.repeat | 不 |
不 |
不 |
qint8, qint16 | Tensor.dtype | ||
| torch.Tensor.reshape | 不 |
不 |
不 |
Tensor.dtype | |||
| torch.Tensor.tile | 不 |
不 |
不 |
qint8, qint16 | Tensor.dtype | ||
| torch.Tensor.abs | 不 |
不 |
不 |
qint8, qint16 | Tensor.dtype |
torchvision 类
| 算子 | eager 模式 |
Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| 输入 | 输出 | 其它 |
输入 | 输出 | 其它 |
||
| torchvision.models.detection.rpn.AnchorGenerator | horizon.nn.AnchorGenerator | qint8,qint16,qint32,float32 | float32 | 仅 |
qint8,qint16,qint32,float32 | float32 | 支持 |
| torchvision.ops.MultiScaleRoIAlign | horizon.nn.MultiScaleRoIAlign | 参考 torchvision.ops.RoIAlign | 参考 torchvision.ops.RoIAlign | 参考 torchvision.ops.RoIAlign | 参考 torchvision.ops.RoIAlign | 参考 torchvision.ops.RoIAlign | 参考 torchvision.ops.RoIAlign |
| torchvision.ops.RoIAlign | qint8 | qint8 | qint8 | qint8 | 1<=feature number<=5;bbox 仅 |