6.4.6. Appendix
6.4.6.1. Eager Mode
Similar to the official PyTorch implementation, we recommend users prioritize the fx quantization mode. Currently, horizon_plugin_pytorch supports quantization using eager mode.
The overall workflow of eager mode follows the official PyTorch quantization APIs and design principles. Therefore, we recommend that you first read the PyTorch Official Documentation regarding the eager mode.
Differences from FX Mode
When using eager mode in horizon_plugin_pytorch, the main differences compared to fx mode are:
Eager mode only supports module-form operators. You must manually replace function-form operators in your floating-point model with module-type operators from PyTorch or proprietary operators defined in
horizon_plugin_pytorch, including but not limited to:
| Original Floating-Point Operator | Replacement Operator |
|---|---|
| torch.nn.functional.relu | torch.nn.ReLU() |
| a + b torch.add |
horizon.nn.quantized.FloatFunctional().add |
| Tensor.exp | horizon.nn.Exp() |
| torch.nn.functional.interpolate | horizon.nn.Interpolate() |
You must manually define the operators to be fused and explicitly call the fusion function, specifying the
fuser_funcprovided byhorizon_plugin_pytorch. For example:
import torch
from torch import nn
import horizon_plugin_pytorch as horizon


class ConvBNReLU(nn.Sequential):
    def __init__(self, in_channels, out_channels, kernel_size):
        super(ConvBNReLU, self).__init__(
            nn.Conv2d(
            in_channels=in_channels,
            out_channels=out_channels,
            kernel_size=kernel_size
            ),
            nn.BatchNorm2d(num_features=out_channels),
            nn.ReLU()
        )

    # Specify operators that can be fused
    def fuse_model(self):
        torch.quantization.fuse_modules(
            self,
            ['0', '1', '2'],
            inplace=True,
            # Specify the fuse function provided by horizon_plugin_pytorch
            fuser_func=horizon.quantization.fuse_known_modules,
        )

float_model = ConvBNReLU(1, 1, 1)
# Must explicitly call the fuse function
float_model.fuse_model()

print(float_model)
# ConvBNReLU(
#   (0): ConvReLU2d(
#     (0): Conv2d(1, 1, kernel_size=(1, 1), stride=(1, 1))
#     (1): ReLU()
#   )
#   (1): Identity()
#   (2): Identity()
# )
Workflow
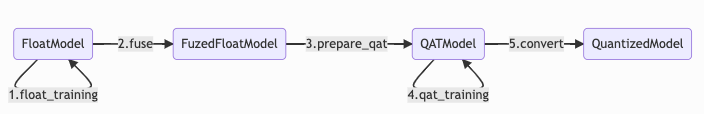
The overall workflow for quantization-aware training (QAT) in eager mode is shown in the diagram below:
Construct Floating-Point Model
When constructing the floating-point model in eager mode, please note the following:
Insert quantization and de-quantization nodes into the network. Typically, a quantization node should be inserted at the beginning of the floating-point model, and a de-quantization node at the end. After the floating-point model is converted to a QAT-ready model, the inserted quantization node will perform quantization on the input;
Some function-form floating-point operators need to be replaced with Module-inherited operators from PyTorch or proprietary operators provided by the plugin;
Define fusion functions for floating-point operators to fuse compatible ones.
import torch
import torch.optim as optim
import horizon_plugin_pytorch as horizon
import os
from torch import nn
from torchvision import datasets, transforms
from torch.quantization import DeQuantStub
from horizon_plugin_pytorch.quantization import QuantStub

class ConvBNReLU(nn.Sequential):
    def __init__(self, in_channels, out_channels, kernel_size):
        super(ConvBNReLU, self).__init__(
            nn.Conv2d(
            in_channels=in_channels,
            out_channels=out_channels,
            kernel_size=kernel_size
            ),
            nn.BatchNorm2d(num_features=out_channels),
            nn.ReLU()
        )

    # Specify floating-point operators that can be fused
    def fuse_model(self):
        torch.quantization.fuse_modules(
            self,
            ['0', '1', '2'],
            inplace=True,
            fuser_func=horizon.quantization.fuse_known_modules,
        )

class ClassiFier(nn.Module):
    def __init__(self, in_channels, out_channels):
        super(ClassiFier, self).__init__()
        self.conv = nn.Conv2d(in_channels, out_channels, 1)

    def forward(self, data):
        return self.conv(data)

# Construct floating-point model
class Net(nn.Module):
    def __init__(self):
        super(Net, self).__init__()
        self.conv0 = ConvBNReLU(1, 10, 5)
        self.max_pool = nn.MaxPool2d(kernel_size=2)
        self.conv1 = ConvBNReLU(10, 20, 5)
        self.avg_pool = nn.AvgPool2d(kernel_size=8)
        self.classifier = ClassiFier(20, 10)
        # To adapt to BPU, when input is from camera, scale of QuantStub must be explicitly set to 1/128
        self.quant = QuantStub(scale=1/128)
        self.dequant = DeQuantStub()

    def forward(self, x):
        # Insert quantization node to quantize input
        x = self.quant(x)
        x = self.conv0(x)
        x = self.max_pool(x)
        x = self.conv1(x)
        x = self.avg_pool(x)
        x = self.classifier(x)
        # Insert de-quantization node to de-quantize output
        x = self.dequant(x)
        return x

    # Define fusion function
    def fuse_model(self):
        from horizon_plugin_pytorch import quantization

        for m in self.modules():
            if type(m) == ConvBNReLU:
                m.fuse_model()
Pre-train Floating-Point Model
train_batch_size = 16
test_batch_size = 16
epoch_num = 1
neval_batches = 1
model_file = 'model.pt'

class AverageMeter(object):
    """Computes and stores the average and current value"""

    def __init__(self, name, fmt=":f"):
        self.name = name
        self.fmt = fmt
        self.reset()

    def reset(self):
        self.val = 0
        self.avg = 0
        self.sum = 0
        self.count = 0

    def update(self, val, n=1):
        self.val = val
        self.sum += val * n
        self.count += n
        self.avg = self.sum / self.count

    def __str__(self):
        fmtstr = "{name} {val" + self.fmt + "} ({avg" + self.fmt + "})"
        return fmtstr.format(**self.__dict__)

criterion = nn.CrossEntropyLoss()

def accuracy(output, target, topk=(1,)):
    """Computes the accuracy over the k top predictions for the specified
    values of k
    """
    with torch.no_grad():
        maxk = max(topk)
        batch_size = target.size(0)

        _, pred = output.topk(maxk, 1, True, True)
        pred = pred.t()
        correct = pred.eq(target.view(1, -1).expand_as(pred))

        res = []
        for k in topk:
            correct_k = correct[:k].reshape(-1).float().sum(0, keepdim=True)
            res.append(correct_k.mul_(100.0 / batch_size))
        return res


def get_train_data_loader():
    train_loader = torch.utils.data.DataLoader(
        datasets.MNIST(
            'mnist_data',
            train=True,
            download=True,
            transform=transforms.Compose(
                [transforms.ToTensor(),
                 transforms.Normalize((0.5,), (0.5,))]
            )
        ),
        batch_size=train_batch_size,
        shuffle=True,
    )
    return train_loader

def get_test_data_loader():
    train_loader = torch.utils.data.DataLoader(
        datasets.MNIST(
            'mnist_data',
            train=False,
            download=True,
            transform=transforms.Compose(
                [transforms.ToTensor(),
                 transforms.Normalize((0.5,), (0.5,))]
            )
        ),
        batch_size=test_batch_size,
        shuffle=True,
    )
    return train_loader

data_loader = get_train_data_loader()
test_loader = get_test_data_loader()

def train(model, device, optimizer, epoch):
    global min_loss
    model.train()
    for batch_idx, (data, target) in enumerate(data_loader):
        data = data.to(device)
        target = target.to(device)
        output = model(data)
        output = output.view(-1, 10)
        loss = criterion(output, target)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()
        if batch_idx %  100 == 0:
            print ('Train Epoch: {} batch {} \t Loss: {:.6f}'.
                format(epoch, batch_idx, loss.item()))

def evaluate(model, device, neval_batches):
    model.eval()
    top1 = AverageMeter("Acc@1", ":6.2f")
    top5 = AverageMeter("Acc@5", ":6.2f")
    tested_batches = 0
    with torch.no_grad():
        for batch_idx, (data, target) in enumerate(test_loader):
            tested_batches += 1
            data = data.to(device)
            target = target.to(device)
            output = model(data)
            output = output.view(-1, 10)
            loss = criterion(output, target)
            acc1, acc5 = accuracy(output, target, topk=(1, 5))
            top1.update(acc1[0], data.size(0))
            top5.update(acc5[0], data.size(0))
            if tested_batches >= neval_batches:
                return top1, top5

    return top1, top5


def train_float_model(device):
    model = Net().to(device)
    optimizer = optim.SGD(model.parameters(), lr=0.001, momentum=0.1)
    for nepoch in range(epoch_num):
        train(model, device, optimizer, nepoch)
        top1, top5 = evaluate(model, device, neval_batches)
        print(
            "float training Epoch %d :float evaluation accuracy on %d images, \
            %2.2f" % (nepoch, neval_batches * test_batch_size, top1.avg)
        )
    torch.save(model.state_dict(), model_file)

train_float_model(torch.device('cuda'))
If you want to perform quantization-aware training based on an existing floating-point model, you can first load the floating-point model and then proceed with operator fusion and quantization training steps. If quantization training follows immediately after floating-point training, there is no need to explicitly reload the model—just proceed directly.
def load_model():
    model = Net()
    state_dict = torch.load(model_file)
    model.load_state_dict(state_dict)
    model.to('cpu')
    return model

qat_model = load_model()
Set BPU Architecture
# Set march **X3** to BERNOULLI2, **X5** to BAYES_E.
horizon.march.set_march(horizon.march.March.BAYES_E)
Operator Fusion
qat_model.fuse_model()
Convert Floating-Point Model to Quantized Model
def load_and_prepare_qat_model(device):
    # Load pre-trained floating-point model
    global qat_model
    qat_model = qat_model.to(device)
    top1, top5 = evaluate(qat_model, device, neval_batches)
    print(
        "float evaluation accuracy on %d images, \
        %2.2f" % (neval_batches * test_batch_size, top1.avg)
    )
    # Set quantization configuration for QAT to specify how weights and outputs are quantized
    qat_model.qconfig = horizon.quantization.get_default_qat_qconfig()
    # Disable quantization on output layer to improve output accuracy
    qat_model.classifier.qconfig = \
        horizon.quantization.get_default_qat_out_qconfig()
    # Convert floating-point model to quantized model
    horizon.quantization.prepare_qat(qat_model, inplace=True)
    print(
        "After preparation for QAT, note fake-quantization modules \n",
        qat_model.conv0,
    )
    qat_model = qat_model.to(device)

load_and_prepare_qat_model(torch.device('cuda'))
Quantization Training
def quantization_training(device):
    # Perform quantization training on the quantized model
    optimizer = optim.SGD(qat_model.parameters(), lr=0.0001)
    for nepoch in range(1):
        train(qat_model, device, optimizer, nepoch)
        # Evaluate quantized model after one epoch
        top1, top5 = evaluate(qat_model, device, neval_batches)
        print(
            "QAT Epoch %d :float evaluation accuracy on %d images, %2.2f"
            % (nepoch, neval_batches * test_batch_size, top1.avg)
        )

quantization_training(torch.device('cuda'))
Convert Quantized Model to Fixed-Point Model
quantized_model = horizon.quantization.convert(
    qat_model.eval(), inplace=False
)
Check and Compile Fixed-Point Inference Model
def compile_quantized_model(device):
    example_input = torch.ones(size=(neval_batches, 1, 28, 28), device=device)
    traced_model = torch.jit.trace(quantized_model, example_input)
    top1, top5 = evaluate(traced_model, device, neval_batches)
    print(
        "Traced : int evaluation accuracy on %d images, %2.2f"
        % (neval_batches * test_batch_size, top1.avg)
    )

    # Check whether the model can be compiled by hbdk. hbdk is a tool for compiling fixed-point models.
    horizon.quantization.check_model(quantized_model, example_input, advice=1)
    hbdk_dir = "hbdk_model"
    if not os.path.exists(hbdk_dir):
        os.mkdir(hbdk_dir)

    # Compile the model; the file model.hbm under hbdk_model is the compiled on-board model
    horizon.quantization.compile_model(
        traced_model, [example_input], opt=2, hbm=hbdk_dir + "/model.hbm"
    )
    # Perform static performance analysis
    horizon.quantization.perf_model(
        traced_model,
        [example_input],
        opt=2,
        input_source=["pyramid"],
        layer_details=True,
        out_dir=hbdk_dir,
    )
    horizon.quantization.visualize_model(
        traced_model,
        [example_input],
        save_path=hbdk_dir + "/model.svg",
        show=False,
    )

compile_quantized_model(torch.device('cuda'))
6.4.6.2. Supported Public Operators
General Notes
Unless otherwise specified, the Bernoulli2 architecture restricts operator inputs and outputs to 4 dimensions.
In eager mode, some operators require manual replacement; in fx mode, no manual replacement is needed.
The supported operators listed below are not fused by default. For operators that can be fused (e.g., (conv, bn), relu), refer to the Operator Fusion section.
During inference, pass-through operators (e.g., Identity, Dropout) will be optimized out during deployment.
torch function class
| Operator | Replacement in Eager Mode | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torch.abs | Not supported | qint8, qint16 | Same as input | ||||
| torch.acos | horizon.nn.Acos | Not supported | qint8, qint16 | qint8, qint16 | Implemented via lookup table, precision risk | ||
| torch.acosh | horizon.nn.Acosh | Not supported | Refer to torch.acos | ||||
| torch.add | torch.nn.quantized.FloatFunctional or horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | in_channel<=2048, constant operands not supported | qint8, qint16 | qint8, qint16 | Supports broadcasting except along N-dim, only one input may broadcast; if one operand is scalar, use add_scalar |
| torch.argmax | Refer to torch.max | Refer to torch.max | |||||
| torch.argmin | Refer to torch.max | Refer to torch.max | |||||
| torch.asin | horizon.nn.Asin | Not supported | Refer to torch.acos | ||||
| torch.asinh | horizon.nn.Asinh | Not supported | Refer to torch.acos | ||||
| torch.atan | horizon.nn.Atan | Not supported | Refer to torch.acos | ||||
| torch.atanh | horizon.nn.Atanh | Not supported | Refer to torch.acos | ||||
| torch.cat | torch.nn.quantized.FloatFunctional or horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | qint8, qint16 | qint8, qint16 | input shape: [N, C, H, W], N<=4096, HWC<=65536, 2<=number of inputs<=1024 | |
| torch.ceil | horizon.nn.Ceil | Not supported | qint8, qint16 | Same as input | Input magnitude should not exceed 1e6 for int8, 1e8 for int16. | ||
| torch.clamp | Not supported | qint8, qint16 | Same as input | Supports min/max as Tensor/constant Tensor/scalar/None. If constant Tensor, data range of min/max should match input, otherwise precision risk exists | |||
| torch.clip | Not supported | Refer to torch.clamp | |||||
| torch.cos | horizon.nn.Cos | Not supported | Refer to torch.acos | ||||
| torch.cosh | horizon.nn.Cosh | Not supported | Refer to torch.acos | ||||
| torch.div | horizon.nn.Div | Not supported | qint16 | qint16 | |||
| torch.eq | Not supported | qint8, qint16 | qbool | ||||
| torch.erf | horizon.nn.Erf | Not supported | Refer to torch.acos | ||||
| torch.exp | horizon.nn.Exp | qint8 | qint8 | Uses table lookup with approximation, precision risk | Refer to torch.acos | ||
| torch.floor | horizon.nn.Floor | Not supported | qint8, qint16 | Same as input | Input magnitude should not exceed 1e6 for int8, 1e8 for int16. | ||
| torch.gather | Not supported | qint8, qint16, qint32 | Same as input | ||||
| torch.ge | Not supported | Refer to torch.eq | |||||
| torch.greater | Not supported | Refer to torch.eq | |||||
| torch.greater_equal | Not supported | Refer to torch.eq | |||||
| torch.gt | Not supported | Refer to torch.eq | |||||
| torch.le | Not supported | Refer to torch.eq | |||||
| torch.less | Not supported | Refer to torch.eq | |||||
| torch.less_equal | Not supported | Refer to torch.eq | |||||
| torch.log | horizon.nn.HardLog | Not supported | Refer to torch.acos | ||||
| torch.lt | Not supported | Refer to torch.eq | |||||
| torch.matmul | horizon.nn.quantized.FloatFunctional | qint8 | qint8, qint32 | qint8, qint16, qint32 | input shape: [N, C, H, W], input_size<1 G bytes, N<=4096, C, H, W<=8192. | ||
| torch.max | qint8 | Same as input | Can only be used as model output. Output format differs from torch: compiler supports one Tensor with max_value in one channel and max_value_index in another | qint8, qint16 | out: qint8, qint16 index: int32 | index can only be model output. input_shape: [N, C, H, W], 1<=N<=4096, 1<=H, W, C<=65535 Supports min/max as Tensor/constant Tensor/scalar/None. When constant Tensor, data range should match input, otherwise precision risk | |
| torch.maximum | horizon.nn.quantized.FloatFunctional | Not supported | input: qint8, qint16 other: qint8, qint16 |
qint8, qint16 | |||
| torch.mean | horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | Only supports mean along channel dimension. QAT has training parameters; avoid standalone use in inference. | qint8, qint16 | qint8, qint16 | Supports mean over CHW. QAT has quantization parameters |
| torch.min | Not supported | Refer to torch.max | |||||
| torch.minimum | horizon.nn.quantized.FloatFunctional | Not supported | Refer to torch.maximum | ||||
| torch.mul | torch.nn.quantized.FloatFunctional or horizon.nn.quantized.FloatFunctional | Refer to torch.add | Refer to torch.add | ||||
| torch.pow | horizon.nn.Pow | Not supported | Refer to torch.acos | ||||
| torch.reciprocal | horizon.nn.Reciprocal | Not supported | Refer to torch.acos | ||||
| torch.selu | horizon.nn.Selu | Not supported | Refer to torch.acos | ||||
| torch.sin | horizon.nn.Sin | Not supported | Refer to torch.acos | ||||
| torch.sinh | horizon.nn.Sinh | Not supported | Refer to torch.acos | ||||
| torch.split | qint8, qint16 | Same as input | qint8, qint16 | Same as input | |||
| torch.sqrt | horizon.nn.Sqrt | Not supported | Refer to torch.acos | ||||
| torch.sub | horizon.nn.quantized.FloatFunctional | qint8, qint16 | qint8, qint16 | in_channel<=2048 | qint8, qint16 | qint8, qint16 | Supports broadcasting except along N-dim, only one input may broadcast. |
| torch.sum | horizon.nn.quantized.FloatFunctional | qint8 | qint8, qint32 | Only supports sum along batch and channel dimensions. | qint8, qint16 | qint8, qint16 | Only supports sum over HWC dimensions |
| torch.tan | horizon.nn.Tan | Not supported | Refer to torch.acos | ||||
| torch.topk | Not supported | qint8, qint16, qint32 | Same as input |
torch.nn.functional function class
| Operator | Replacement in Eager Mode | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torch.nn.functional.grid_sample | Not supported | Not supported | Not supported | input: qint8 grid: qint8, qint16 |
qint8 | Input shape: [N, C, H, W], 1<=H, W<=1024 and HW<=7201024; grid supports qint8 and qint16, only bilinear and nearest interpolation supported; padding modes only support zeros and border; | |
| torch.nn.functional.interpolate | qint8 | qint8 | Supports nearest and bilinear interpolation modes. 1/256 < scale ratio <= 256 | qint8 | qint8 | Only supports nearest and bilinear interpolation modes. input_shape: [N, C, H, W], 1<=C, H, W<=8192; align_corners supports False and None; when scale=[] is used, recompute_scale_factors must be True | |
| torch.nn.functional.pad | Not supported | Not supported | Not supported | qint8, qint16 | Same as input | reflect mode not supported | |
| torch.nn.functional.relu | torch.nn.ReLU | qint8 | qint8 | qint8 | Same as input | Pattern Conv2d+BN+ReLU will be automatically fused | |
| torch.nn.functional.relu6(fused) | torch.nn.ReLU6 | qint8 | Same as input |
torch.nn Module class
| Operator | Replacement in Eager Mode | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torch.nn.AdaptiveAvgPool2d | Not supported | Not supported | Not supported | qint8 | Same as input | Constructed using AvgPool2d with non-equivalent operations, has accuracy issues | |
| torch.nn.AvgPool2d | qint8 | Same as input | 1<=kernel<=7, 1<=stride<=185 | 1<=kernel, stride, padding<=256; | |||
| torch.nn.BatchNorm2d | BatchNorm2d is absorbed during QAT phase and does not appear in the inference model. Due to compiler limitations, standalone BatchNorm2d uses BpuConvolution at the underlying level | qint8 | qint8 | BatchNorm2d is absorbed during QAT phase and thus does not appear in the model. Standalone usage restrictions refer to Conv2d | |||
| torch.nn.BatchNorm3d | BatchNorm3d is absorbed during QAT phase and does not appear in the inference model. Due to compiler limitations, standalone BatchNorm3d uses BpuConvolution at the underlying level | qint8 | qint8 | BatchNorm3d is absorbed during QAT phase and thus does not appear in the model. Standalone usage restrictions refer to Conv2d | |||
| torch.nn.ChannelShuffle | qint8 | Same as input | qint8, qint16 | Same as input | Values in shuffle_index must not repeat | ||
| torch.nn.ConstantPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | |||
| torch.nn.Conv2d | qint8 | qint8, qint32 | input: qint8, qint16; weight: qint8; bias: qint32 | qint8, qint16, qint32 | out_channel<=8192, when used as model output, out_channel <= 16384. Input channel<=8192, kernel<32, dilation<=16, when dilation!=1, stride must be 1. Supports sumin, conv with sumin only supports stride of (1, 1) or (2, 2). weight_shape: [N, C, H, W], N, C<=8192, H, W<=31, as model output C<=16384, weight_size < 65535. padding<=256 When input is qint16, the accumulated sum must not exceed int32 range | ||
| torch.nn.Conv3d | Not supported | Not supported | Not supported | input: qint8, weight: qint8, bias: qint32 | qint8 | input: [N, C, D, H, W] int8, N<=128; H, W, D, C<=65536; weight: [C_o, C_i, D, H, W] int8, N, C<=65536, D, H<=9, W<=8191; bias: int32; output: [N, C, D, H, W] int8, int16, int32; stride: [D, H, W], D, H, W equal to 1 or 2, and D, H, W are the same; padding: [D, H, W], D<=kernel_d/2, H<=kernel_h/2, W<=kernel_w/2 (kernel_w refers to the size of weight W dimension); group, dilation: not supported | |
| torch.nn.ConvTranspose2d | qint8 | qint8 | 2<=kernel<=14. channel<=2048. padding H*W=[0, (kernel_h-1)/2] * [0, (kernel_w-1)/2] 2<=stride<=4, dilation=(1, 1) | qint8 | qint8 | Input shape: [N, C, H, W], 1<=N<=128, 1<=channel<=2048; weight_shape: [N, C, H, W], 1<=N, C<=2048, 2<=H, W<=14, weight_size<=65535; kernel>=stride, 1<=stride<=14, 1<=out_channel<=2048, in_channel<=2048 pad<=kernel/stride, 0<=out_pad<=1; bias type is int32; supports sumin, sumin input type is int8; 0<=output_padding<=1; supports group, requires weight_n and input channel both divisible by group; dilation=1 | |
| torch.nn.Dropout | qint8, qint16, qint32 | Same as input | qint8, qint16, qint32 | Same as input | |||
| torch.nn.Dropout2d | qint8, qint16, qint32 | Same as input | qint8, qint16, qint32 | Same as input | |||
| torch.nn.ELU | Not supported | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.GELU | Refer to torch.exp | Refer to torch.exp | Refer to torch.exp | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.GLU | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | |||
| torch.nn.HardSigmoid | Not supported | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.Identity | qint8, qint16, qint32 | Same as input | qint8, qint16, qint32 | Same as input | |||
| torch.nn.Layernorm | Not supported | Not supported | Not supported | qint8 | qint8, qint16 | Implemented using multiple table lookups, high precision risk. Internal rsqrt lookup parameters can be controlled via rsqrt_kwargs attribute. If accuracy degradation occurs during conversion, try layernorm_op.rsqrt_kwargs = {"auto_divide_strategy": "curvature"}. H * W <= 16384, normalized_shape H * W < 16384 | |
| torch.nn.LeakyReLU | Not supported | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.Linear | Not supported | Not supported | Not supported | input: qint8; weight: qint8; bias: qint32 | qint8 | in_features <= 8192, out_features <= 8192. | |
| torch.nn.LSTMCell | Not supported | Not supported | Not supported | qint8, qint16 | qint8, qint16 | Input is 2-dimensional | |
| torch.nn.MaxPool2d | qint8 | Same as input | 1<=kernel<=64, 1<=stride<=256, padding>=0 | qint8 | Same as input | input_shape: [N, C, H, W], 1<=H, W, C<=8192; 1<=kernel, stride<=256; 0<=padding<=255; | |
| torch.nn.MultiheadAttention | Not supported | Not supported | Not supported | qint8, qint16 | qint8, qint16 | Does not support add_bias_kv, add_zero_attn, or inconsistent q k v embed_dim. Supports int8/int16 input/output. Underlying table lookup operators and mask quantization may introduce accuracy risks | |
| torch.nn.PixelShuffle | qint8, qint16 | Same as input | qint8, qint16 | Same as input | |||
| torch.nn.PixelUnshuffle | qint8, qint16 | Same as input | qint8, qint16 | Same as input | |||
| torch.nn.PReLU | Not supported | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.ReLU | qint8 | Same as input | qint8, qint16 | Same as input | |||
| torch.nn.ReLU6 | qint8 | Same as input | qint8, qint16 | Same as input | |||
| torch.nn.ReplicationPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | Refer to torch.nn.ZeroPad2d | ||
| torch.nn.Sigmoid | Refer to torch.exp | Refer to torch.exp | Refer to torch.exp | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.SiLU | Refer to torch.exp | Refer to torch.exp | Refer to torch.exp | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.Softmax | Not supported | Not supported | Not supported | qint8 | qint8, qint16 | Constructed using multiple table lookups, summations, etc., high precision risk | |
| torch.nn.Softplus | Not supported | Not supported | Not supported | Refer to torch.acos | Refer to torch.acos | ||
| torch.nn.SyncBatchNorm | qint8 | qint8 | Constructed using torch.nn.Conv2d | qint8 | qint8 | Constructed using torch.nn.Conv2d | |
| torch.nn.Tanh | Refer to torch.exp | Refer to torch.exp | Refer to torch.exp | Refer to torch.acos | Refer to torch.acos | Refer to torch.acos | |
| torch.nn.Upsample | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | |
| torch.nn.UpsamplingBilinear2d | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | |
| torch.nn.UpsamplingNearest2d | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | Refer to torch.nn.functional.interpolate | |
| torch.nn.ZeroPad2d | qint8 | Same as input | qint8, qint16 | Same as input |
torch.quantization Module Classes
| Operator | Eager Mode Replacement Operator | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torch.quantization.DeQuantStub | qint8, qint16, qint32 | float32 | Typical use case: segmented network models where data needs to be transferred from BPU to CPU for dequantization before further processing on CPU | qint8, qint16, qint32 | float32 | Typical use case: segmented network models where data needs to be transferred from BPU to CPU for dequantization before further processing on CPU | |
| torch.quantization.QuantStub | horizon.quantization.QuantStub | float32 | qint8, qint16 | Typical use case: entire network input or model segmentation scenarios where data is quantized before being sent from CPU to BPU. Scale parameter setting method: scale setting depends on specific inputs. Goal is to quantize float inputs to int8 with maximum precision—requiring both full coverage (or majority) of input values and high quantization precision. Example: if float input range is (-1, 1), set scale = 1 / 128. For pre-trained float models: since the model is already trained, it may not follow this scale setting rule; this can be resolved by inserting a special conv layer. Input to QuantStub must have uniform distribution | float32 | qint8, qint16 | Typical use case: entire network input or model segmentation scenarios where data is quantized before being sent from CPU to BPU. Scale parameter setting method: scale setting depends on specific inputs. Goal is to quantize float inputs to int8 with maximum precision—requiring both full coverage (or majority) of input values and high quantization precision. Example: if float input range is (-1, 1), set scale = 1 / 128. For pre-trained float models: since the model is already trained, it may not follow this scale setting rule; this can be resolved by inserting a special conv layer. Input to QuantStub must have uniform distribution |
torch.Tensor Methods
| Operator | Eager Mode Replacement Operator | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torch.Tensor.getitem | qint8, qint16, qint32 | Same as input | |||||
| torch.Tensor.transpose | Not supported | Not supported | Not supported | qint8, qint16, qint32 | Tensor.dtype | Does not support N-dimensional transpose | |
| torch.Tensor.argmax | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | |
| torch.Tensor.argmin | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | Refer to torch.max | |
| torch.Tensor.clamp | Not supported | Not supported | Not supported | qint8, qint16 | Tensor.dtype | dim <= 10, 1 <= each_dim_size < 65536 | |
| torch.Tensor.clip | Not supported | Not supported | Not supported | Refer to torch.Tensor.clip | Refer to torch.Tensor.clip | Refer to torch.Tensor.clip | |
| torch.Tensor.eq | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.ge | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.greater | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.greater_equal | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.gt | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.le | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.less | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.less_equal | Not supported | Not supported | Not supported | Refer to torch.eq | Refer to torch.eq | Refer to torch.eq | |
| torch.Tensor.max | Not supported | Not supported | Not supported | Refer to torch.max | Refer to torch.max | Refer to torch.max | |
| torch.Tensor.min | Not supported | Not supported | Not supported | Refer to torch.max | |||
| torch.Tensor.repeat | Not supported | Not supported | Not supported | qint8, qint16 | Tensor.dtype | ||
| torch.Tensor.reshape | Not supported | Not supported | Not supported | Tensor.dtype | |||
| torch.Tensor.tile | Not supported | Not supported | Not supported | qint8, qint16 | Tensor.dtype | ||
| torch.Tensor.abs | Not supported | Not supported | Not supported | qint8, qint16 | Tensor.dtype |
torchvision Classes
| Operator | Eager Mode Replacement Operator | Bernoulli2 | Bayes | ||||
|---|---|---|---|---|---|---|---|
| Input | Output | Other Constraints | Input | Output | Other Constraints | ||
| torchvision.models.detection.rpn.AnchorGenerator | horizon.nn.AnchorGenerator | qint8, qint16, qint32, float32 | float32 | Only supports cases where Tensor.shape can be determined offline | qint8, qint16, qint32, float32 | float32 | Supports input int8/int16/int32/float32, output float32 |
| torchvision.ops.MultiScaleRoIAlign | horizon.nn.MultiScaleRoIAlign | Refer to torchvision.ops.RoIAlign | Refer to torchvision.ops.RoIAlign | Refer to torchvision.ops.RoIAlign | Refer to torchvision.ops.RoIAlign | Refer to torchvision.ops.RoIAlign | Refer to torchvision.ops.RoIAlign |
| torchvision.ops.RoIAlign | qint8 | qint8 | qint8 | qint8 | 1<=feature number<=5; bbox only supports List[Tensor] format shape:[1, box_num, 4], last dimension of bbox contains: [left, top, right, bottom] |