Text-to-Speech (TTS)
TTS (Text To Speech) synthesizes natural spoken audio from text. AI algorithms simulate human pronunciation and play the content in real time. TTS is a foundation for intelligent assistants, human-machine interaction, customer service, in-vehicle systems, and robot voice interaction. It improves how devices deliver information and interact naturally.
| Hardware | Model | Performance benchmark |
|---|---|---|
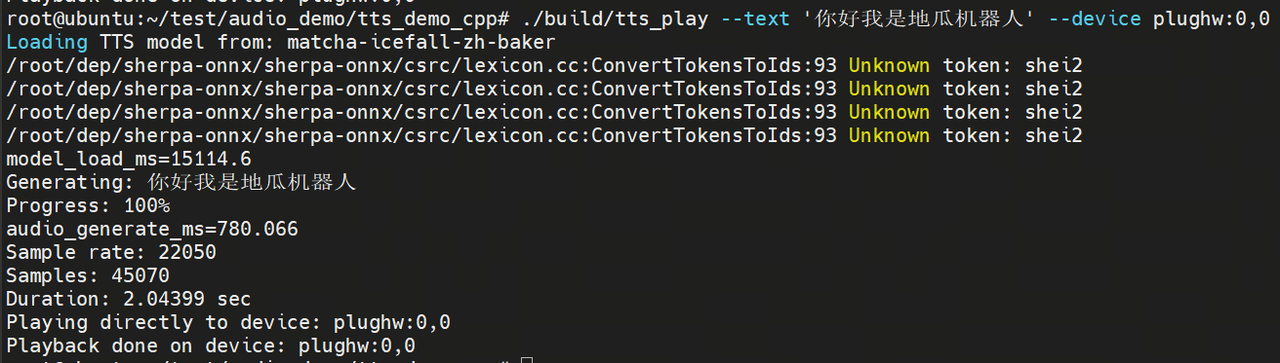
| RDK X5 USB speaker / wired headset | Matcha | Generated text: 你好我是地瓜机器人 (2044 ms) Generation time: 780 ms (8-core CPU) |
Hardware Connection
- Plug a USB speaker into a USB port on the RDK X5 development board.
- Plug a wired headset into the earphone audio jack on the RDK X5 development board.
Environment Setup
Install Dependencies
# Install dependencies
sudo apt update
sudo apt install libasound2-dev
Build sherpa-onnx
Caution
- CMake pulls dependency code. Make sure GitHub is reachable; retry if it fails.
- If you have already built it, skip this step.
git clone https://github.com/k2-fsa/sherpa-onnx.git
cd sherpa-onnx
mkdir build
cd build
cmake -DCMAKE_BUILD_TYPE=Release ..
make -j6
make install .
Get the Sample Code and Build
wget https://archive.d-robotics.cc/downloads/rdk_demo/rdk_x5_demo/tts_demo_cpp.tar.gz
tar zxvf tts_demo_cpp.tar.gz
cd tts_demo_cpp
cmake -S . -B build
cmake --build build -j6
Run the Sample
Tip
- This feature generates audio from the input text and plays it through the speaker.
- To specify the audio device at runtime, see Earphone Audio Jack.
- Model loading takes a moment after startup. Please wait.
# Run from the tts_demo_cpp directory
./build/tts_play --text '你好我是地瓜机器人' --device plughw:0,0